

How Organizations Are Solving Privacy, Scalability, and AI Training Challenges with Artificially Generated Data
In 2026, data has become the foundation of almost every modern business system.
Artificial intelligence, analytics platforms, recommendation engines, autonomous systems, fraud detection models, and predictive business tools all depend heavily on one thing:
Massive amounts of high-quality data.
But organizations are now facing a serious challenge:
- Real-world data is expensive to collect
- Privacy regulations are becoming stricter
- Sensitive datasets are difficult to share
- AI systems require enormous training volumes
As businesses scale their AI initiatives, traditional data strategies are becoming insufficient.
This is why one of the fastest-growing trends in modern enterprise AI is:
Synthetic Data
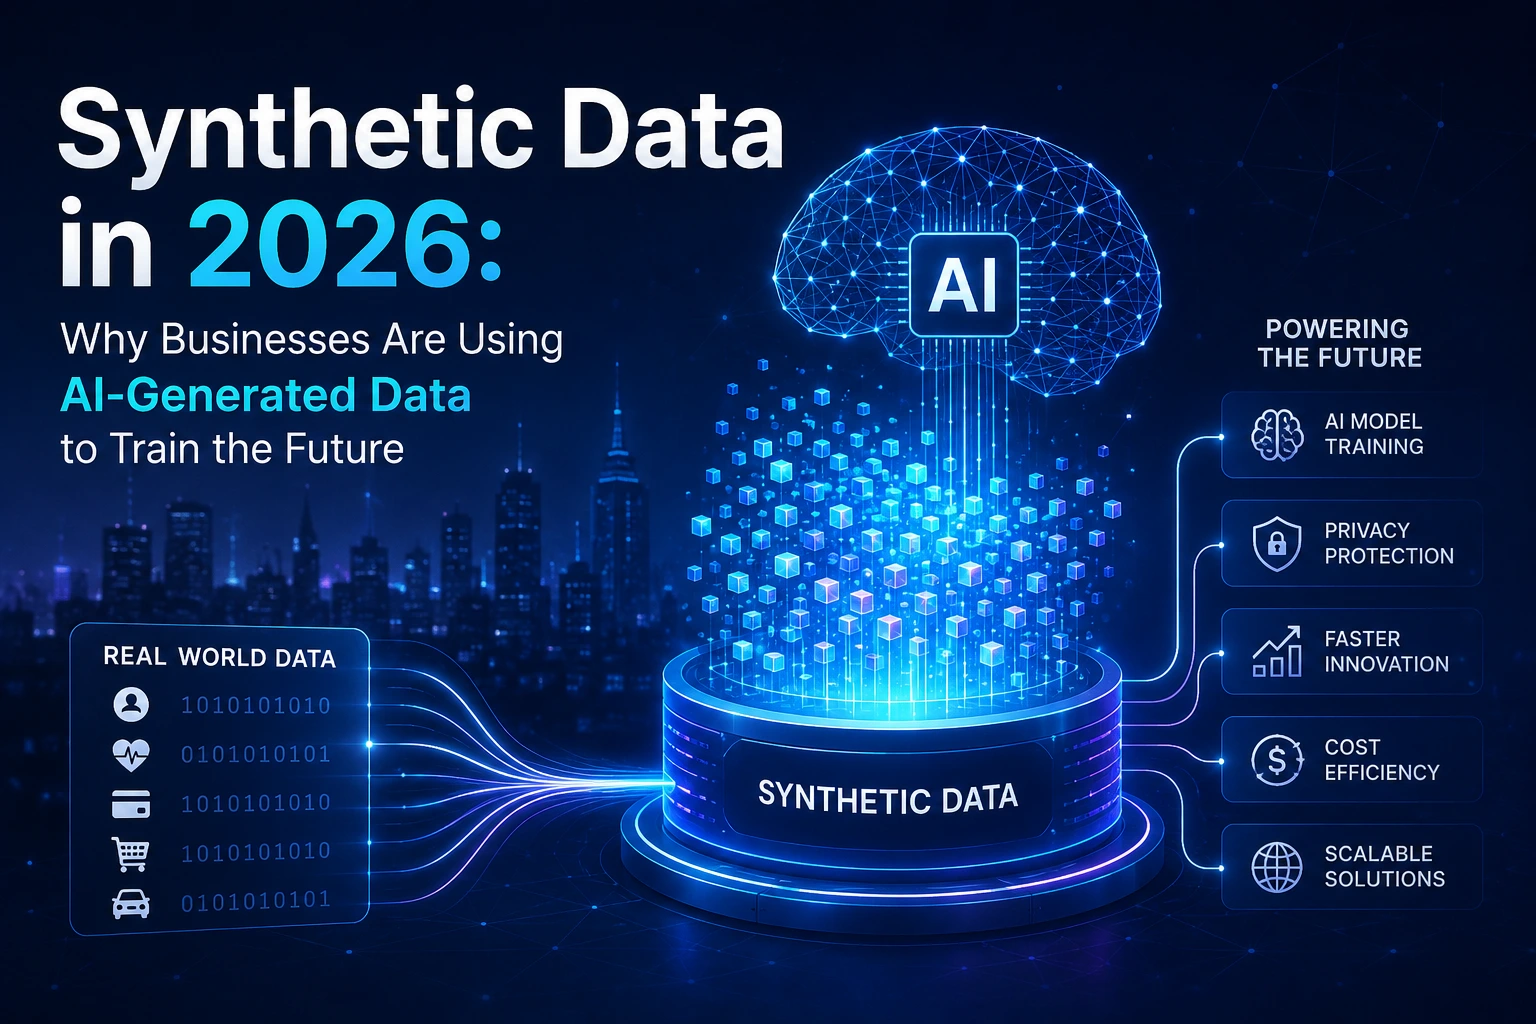
Synthetic data is transforming how organizations build, train, test, and scale intelligent systems.
What Is Synthetic Data?
Synthetic data is artificially generated data created using algorithms, simulations, or AI models instead of being collected directly from real-world events.
The generated data is designed to replicate:
- Patterns
- Behaviors
- Statistical relationships
- Scenarios
found in real datasets without exposing actual sensitive information.
In simple terms:
Synthetic data behaves like real data, but is artificially created.
Why Synthetic Data Is Trending in 2026
Several major shifts are driving rapid adoption.
1. AI Requires Massive Training Data
Modern AI systems need extremely large datasets for training and optimization.
However, acquiring real-world data at scale is often difficult due to:
- Limited availability
- High collection costs
- Legal restrictions
Synthetic data provides scalable alternatives for AI development.
2. Data Privacy Regulations Are Increasing
Global privacy laws continue becoming stricter regarding:
- Personal information
- Healthcare records
- Financial transactions
- User behavior data
Organizations must protect sensitive information while still enabling analytics and AI innovation.
Synthetic data reduces exposure to privacy risks.
3. Real-World Edge Cases Are Rare
AI systems often fail because rare scenarios are underrepresented in training datasets.
For example:
- Fraud detection anomalies
- Rare medical conditions
- Autonomous driving accidents
Synthetic generation allows organizations to simulate and amplify rare situations for better AI training.
How Synthetic Data Works
Synthetic data generation typically uses:
- Machine learning models
- Generative AI
- Statistical modeling
- Simulation systems
These systems analyze real data patterns and generate new datasets that maintain similar characteristics without directly copying original records.
Types of Synthetic Data
Fully Synthetic Data
Entirely AI-generated datasets with no direct real-world records included.
Best for privacy-sensitive use cases.
Partially Synthetic Data
Real datasets are modified or augmented with generated values.
Used when maintaining statistical accuracy is critical.
Simulated Data
Generated through simulation environments.
Common in:
- Autonomous vehicles
- Robotics
- Industrial systems
Real-World Business Use Cases
Healthcare AI
Healthcare organizations use synthetic patient data to:
- Train diagnostic models
- Research treatments
- Share datasets safely
without exposing real patient identities.
Financial Fraud Detection
Banks generate synthetic transaction patterns to train fraud detection systems for rare attack scenarios.
Autonomous Vehicle Training
Self-driving systems rely heavily on simulated driving environments to test:
- Traffic behavior
- Weather conditions
- Accident scenarios
Retail & Customer Analytics
Businesses simulate customer behavior patterns to improve:
- Recommendations
- Demand forecasting
- Marketing optimization
Technologies Powering Synthetic Data
The synthetic data ecosystem is rapidly expanding with platforms such as:
- Gretel.ai
- Mostly AI
- NVIDIA Omniverse
These platforms help organizations generate scalable, privacy-safe datasets.
Data Insight: Why Enterprises Are Investing in Synthetic Data
Organizations adopting synthetic data strategies are reporting major advantages:
- Faster AI development cycles
- Reduced compliance risks
- Improved model training diversity
- Lower data acquisition costs
More importantly:
Synthetic data is becoming a critical enabler for enterprise-scale AI innovation.
Synthetic Data vs Real Data
| Real Data | Synthetic Data |
|---|---|
| Collected from real users/events | Artificially generated |
| Privacy-sensitive | Privacy-safe |
| Expensive to scale | Highly scalable |
| Limited rare scenarios | Easy edge-case generation |
| Compliance challenges | Lower compliance risk |
Synthetic data helps solve many limitations of traditional datasets.
Key Benefits for Businesses
Faster AI Innovation
Teams can generate large datasets instantly instead of waiting for real-world collection.
Enhanced Privacy Protection
Sensitive user information remains protected while still enabling analytics and model training.
Better AI Accuracy
Rare scenarios can be simulated at scale, improving AI robustness.
Reduced Development Costs
Synthetic generation lowers dependency on expensive data collection operations.
Challenges Businesses Must Address
Despite its advantages, synthetic data also introduces important considerations.
Data Quality Validation
Generated datasets must accurately reflect real-world patterns.
Poor synthetic data leads to poor AI performance.
Bias Replication
If original datasets contain bias, synthetic models may reproduce those same biases.
Regulatory Acceptance
Some industries still require validation regarding how synthetic datasets are used in production systems.
The Future: AI Training Without Real-World Limitations
As AI systems become more advanced, the demand for scalable training data will continue increasing exponentially.
Synthetic data is expected to become foundational for:
- Enterprise AI systems
- Autonomous technologies
- Digital twins
- Simulation environments
- Predictive analytics platforms
In many future systems, synthetic data may become more important than collected real-world data itself.
How Our Company Helps Businesses Build AI-Ready Data Ecosystems
At our company, we help organizations modernize their AI and analytics infrastructure using advanced data strategies.
Our expertise includes:
- Synthetic data solutions
- AI training pipelines
- Privacy-focused analytics systems
- Simulation-based data modeling
We help businesses build intelligent systems that are:
- ✅ Scalable
- ✅ Secure
- ✅ AI-ready
- ✅ Future-focused
Final Thoughts
Synthetic Data is rapidly becoming one of the most important technologies behind the future of AI and enterprise analytics.
As privacy regulations tighten and AI demands larger datasets, organizations can no longer rely solely on traditional data collection methods.
Businesses adopting synthetic data strategies early will gain major advantages in:
- AI scalability
- Privacy compliance
- Faster innovation
- Operational flexibility
In 2026, the future of AI is not only powered by data — it is increasingly powered by artificially generated intelligence-ready data.